Deduplicating data without losing information
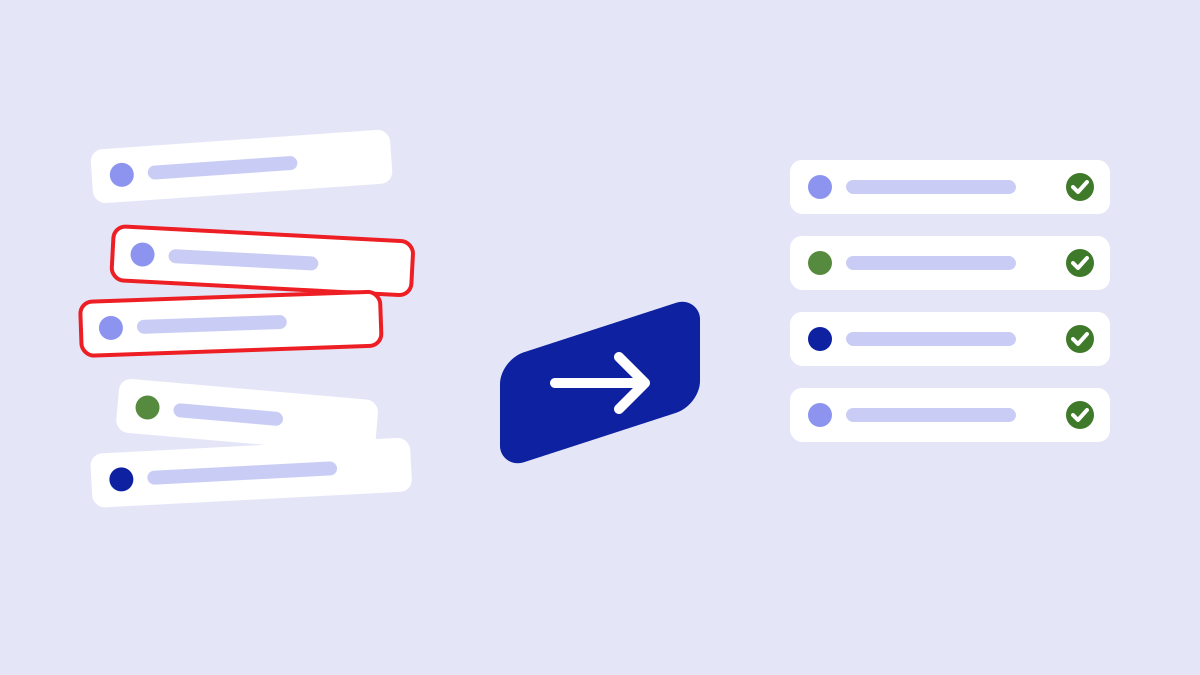
Removing duplicates sounds easy: find the matches and delete one. In practice, each duplicate record can hold different information that matters. Good deduplication merges records rather than just deleting them.
Written by the Mehuli team
01Why duplicates appear
Duplicates usually come from data entered from several sources, by different people, in different formats. One person can appear under a full name in one system and a short name in another.
02Standardize first, then match
Matching is far more accurate once formats are consistent: capitalization, abbreviations, titles, and address formats. Without this step, many duplicates go undetected.
03Set matching rules
Agree on when two records count as the same, such as when name, registration number, and city all match. Uncertain cases are best checked by a person, not decided automatically.
04Keep the best value from each record
When merging, take the most complete and most recent value from each record, such as the email from one record and the address from another.
05Keep a trail
Record which records were merged and why. This trail matters if questions come up later, and makes it easy to fix mistakes.